
GLM-5.2
GLM-5.2 is the flagship model built for the long-task era, featuring a truly usable 1M context window and 128K max output tokens. With GLM-5.2, developers can complete the entire development chain from requirements to deployable artifacts in a single continuous task. GLM-5.2 keeps engineering standards reliable across extended sessions.
Feedback
freeTrialImage.bannerPity
freeTrialImage.upgradeUnlock
- ✓freeTrialImage.benefitHd
- ✓freeTrialImage.benefitWatermark
- ✓freeTrialImage.benefitUnlimited
All Tools
Discover our comprehensive AI-powered animation toolkit
MiniMax H3
MiniMax H3 AI Video Generator
Seedance 2.5
The Future of AI Video Is Here.

Seedance 2.0
The Future of AI Video Is Here.

Seedance 2.0
The Future of AI Video Is Here.

Gemini Omni
Gemini Omni Video Generator
Image to Video
Generate videos from images

Gemini Omni 1.2 Flash

AI Multi-Scene Shorts Generator
Create viral AI Shorts instantly
Inside GLM-5.2: Built for Extended Engineering Sessions
GLM-5.2 is a flagship foundation model designed for work that spans hours, not minutes. It offers a reliable 1M-token context and 128K output ceiling, with tuning for long-range coding agents, large-scale builds, automated research, and performance tuning. Teams can keep architecture rules and code style consistent while carrying an entire project inside one reasoning chain.
- 1M-Token Working MemoryGLM-5.2 gives development teams a practical 1M-token window for multi-file engineering and long-running agent tasks.
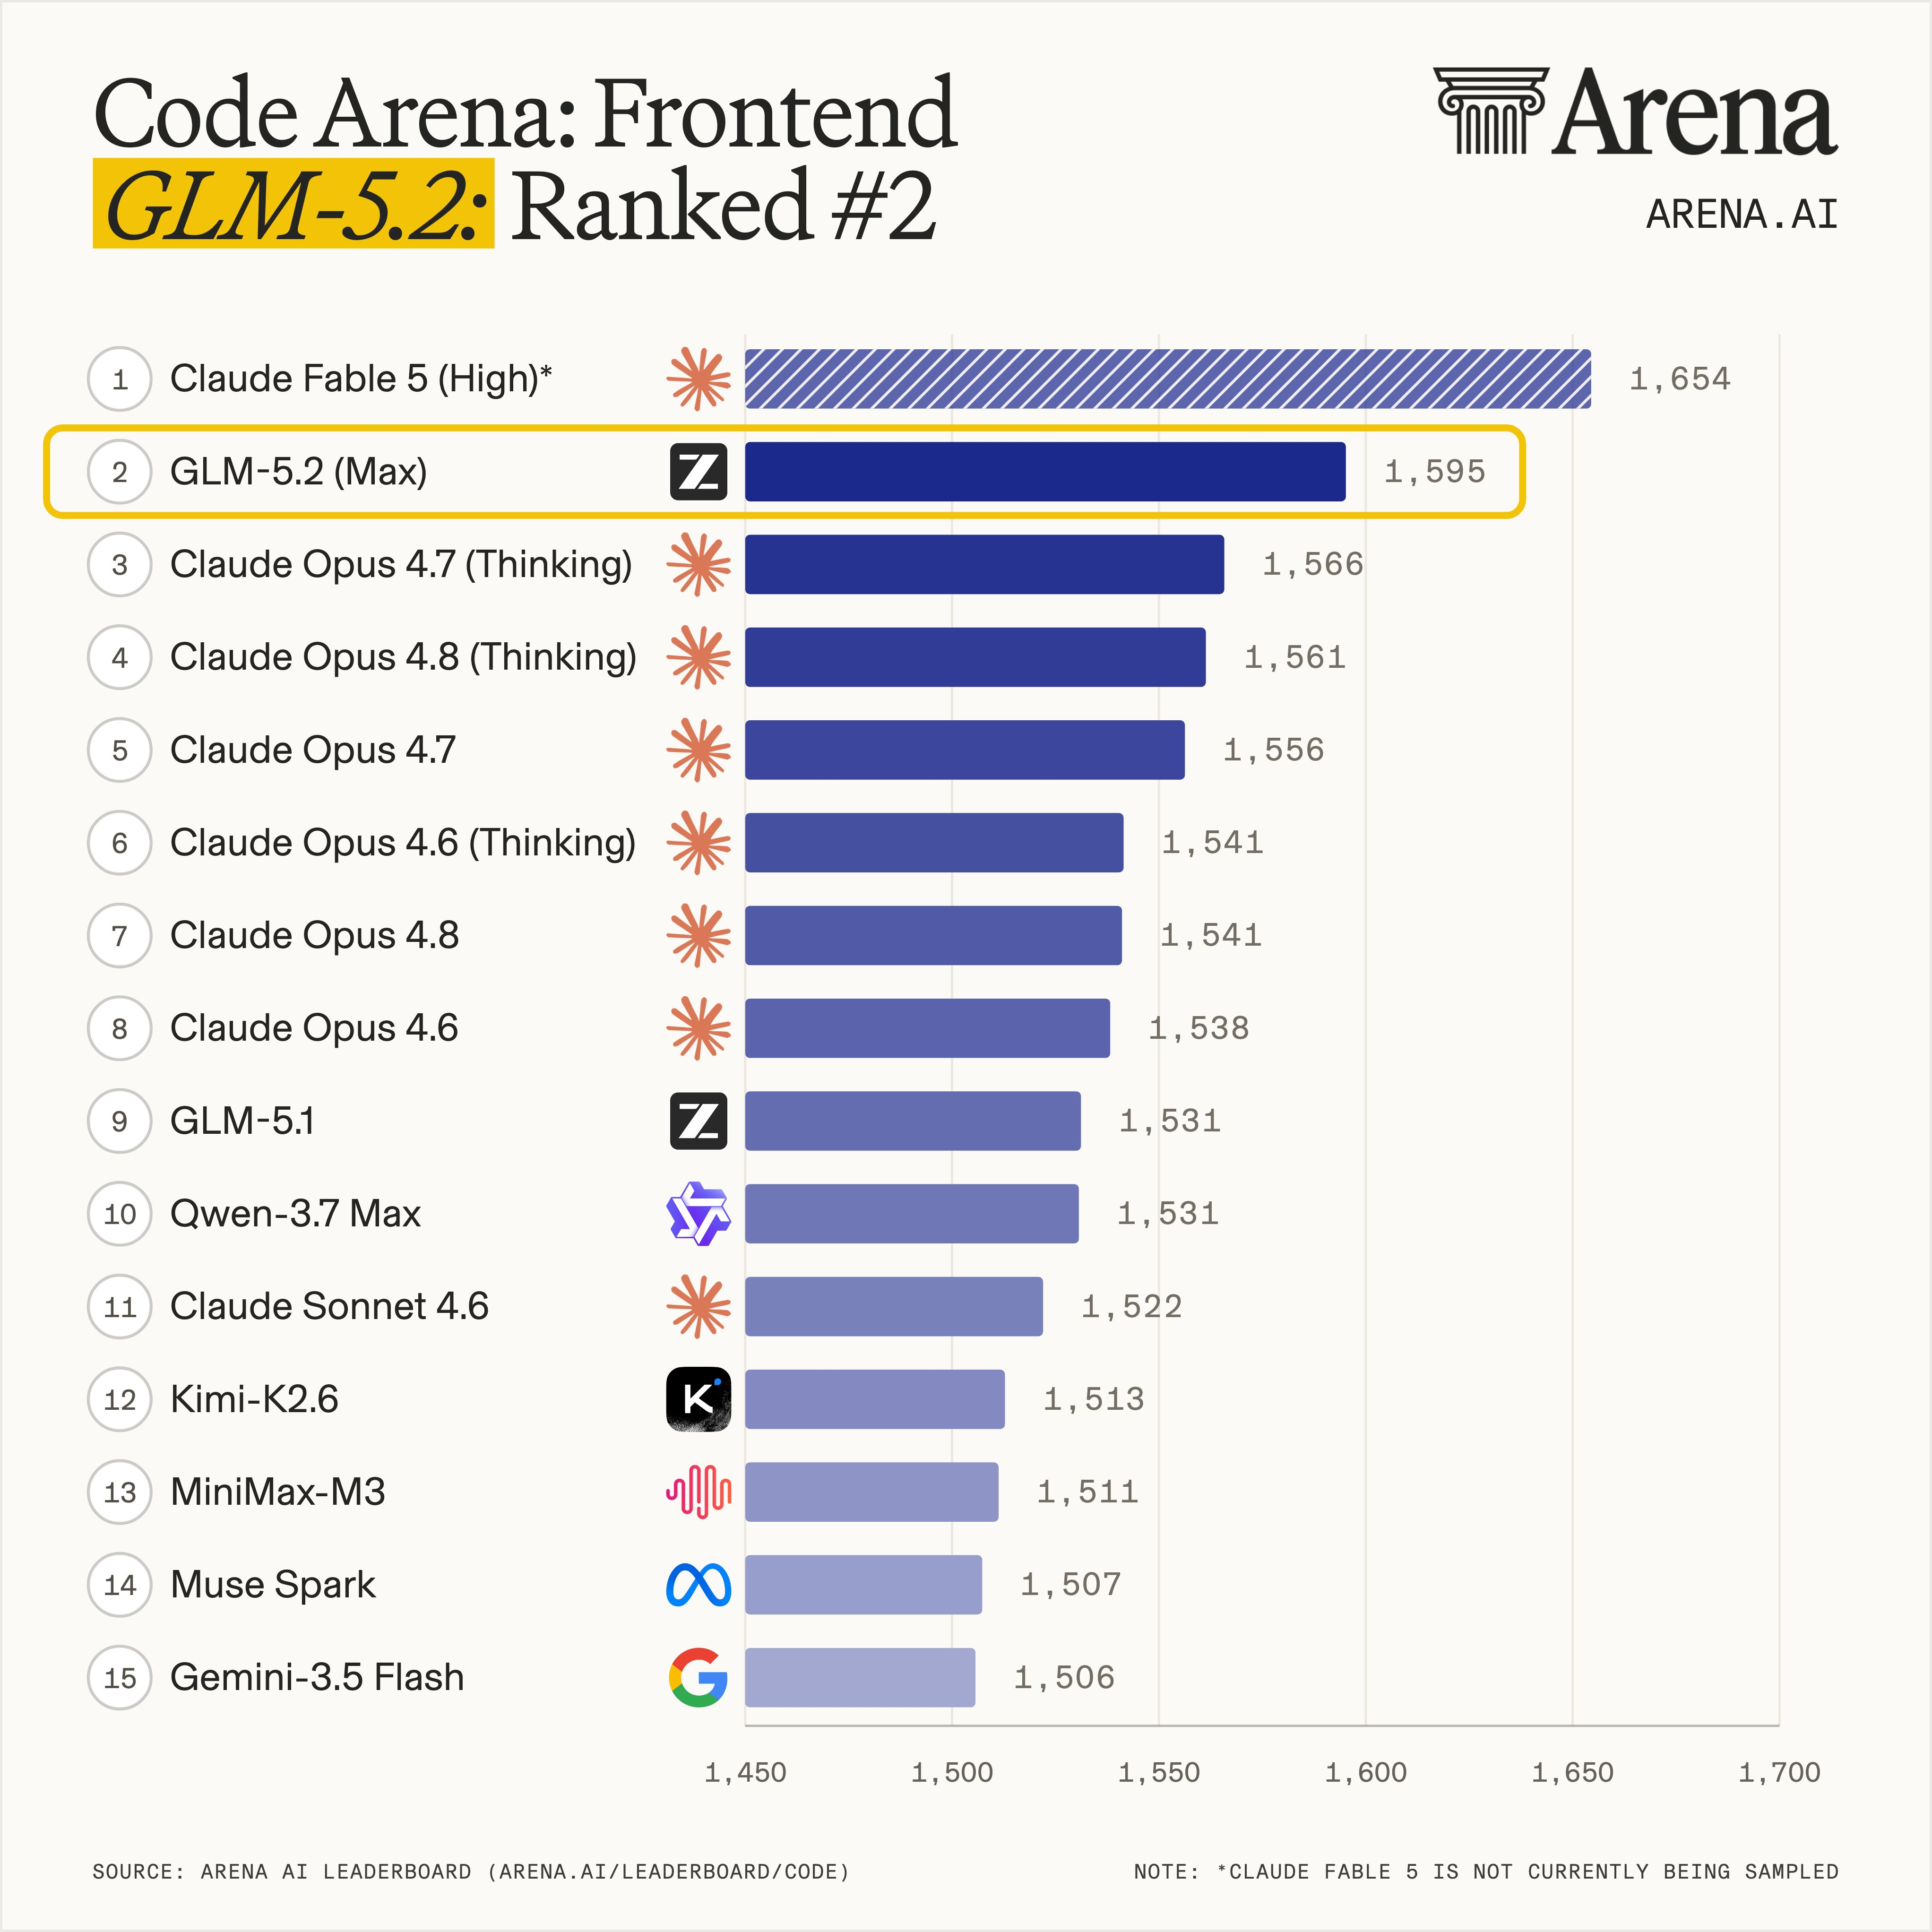
- Top-Tier Coding PerformanceOn widely used coding benchmarks, GLM-5.2 holds open-source SOTA and sits at the top of Code Arena among available models.
- Production-Grade DisciplineGLM-5.2 respects code style, architectural boundaries, and dependency rules across extended sessions, keeping output ready for production review.
Launch GLM-5.2 in Three Steps
Move from setup to deployment with GLM-5.2 in three clear steps for development and video creation workflows.
Capabilities Built into GLM-5.2
GLM-5.2 combines multiple thinking modes, live streaming, function calling, context caching, structured output, and MCP integration to support end-to-end development.
Adaptive Thinking Modes
GLM-5.2 switches between reasoning modes to match task complexity and delivery requirements.
Real-Time Streaming
GLM-5.2 streams responses as they are generated, keeping interactive apps responsive.
Tool and Function Calling
GLM-5.2 connects to external services and tools through robust function-calling support.
Smart Context Caching
GLM-5.2 caches relevant context to speed up long conversations and reduce repeated computation.
Structured Data Output
GLM-5.2 returns JSON and other structured formats for cleaner system integration and data pipelines.
MCP Tool Integration
GLM-5.2 can invoke external MCP tools and data sources to extend workflows and application scenarios.
GLM-5.2 Questions, Answered
Find clear answers about GLM-5.2 context limits, coding performance, speed, and supported project types.
What exactly is GLM-5.2?
GLM-5.2 is a flagship base model for long-running tasks, with a usable 1M-token context and 128K max output for project-level engineering.
Which tasks can GLM-5.2 handle?
GLM-5.2 supports long-range refactoring, mobile device debugging, mini-program and mini-game builds, research replication, and complete project engineering.
How quickly does GLM-5.2 respond?
GLM-5.2 uses streaming output and context caching to keep long sessions responsive and reduce latency on extended tasks.
Does GLM-5.2 perform well on coding work?
GLM-5.2 holds open-source SOTA on mainstream coding benchmarks and ranks first on Code Arena among available models, with quality comparable to Claude Opus 4.8.
How much context can GLM-5.2 process?
GLM-5.2 offers a solid 1M-token lossless context window, so it can handle project-level code and documentation with stable performance.
Which project types are a good fit for GLM-5.2?
GLM-5.2 fits web development, mobile apps, WeChat mini-programs, mini-games, scientific code replication, and coding-to-video workflows.
Put GLM-5.2 to Work Today
Launch your next long-context build with GLM-5.2 and use a practical 1M-token window for real development work.